Schema Diagram and Graph Statistics
Since GraphFrames has no support for printing a graph schema, we reuse the one output from Neo4j.
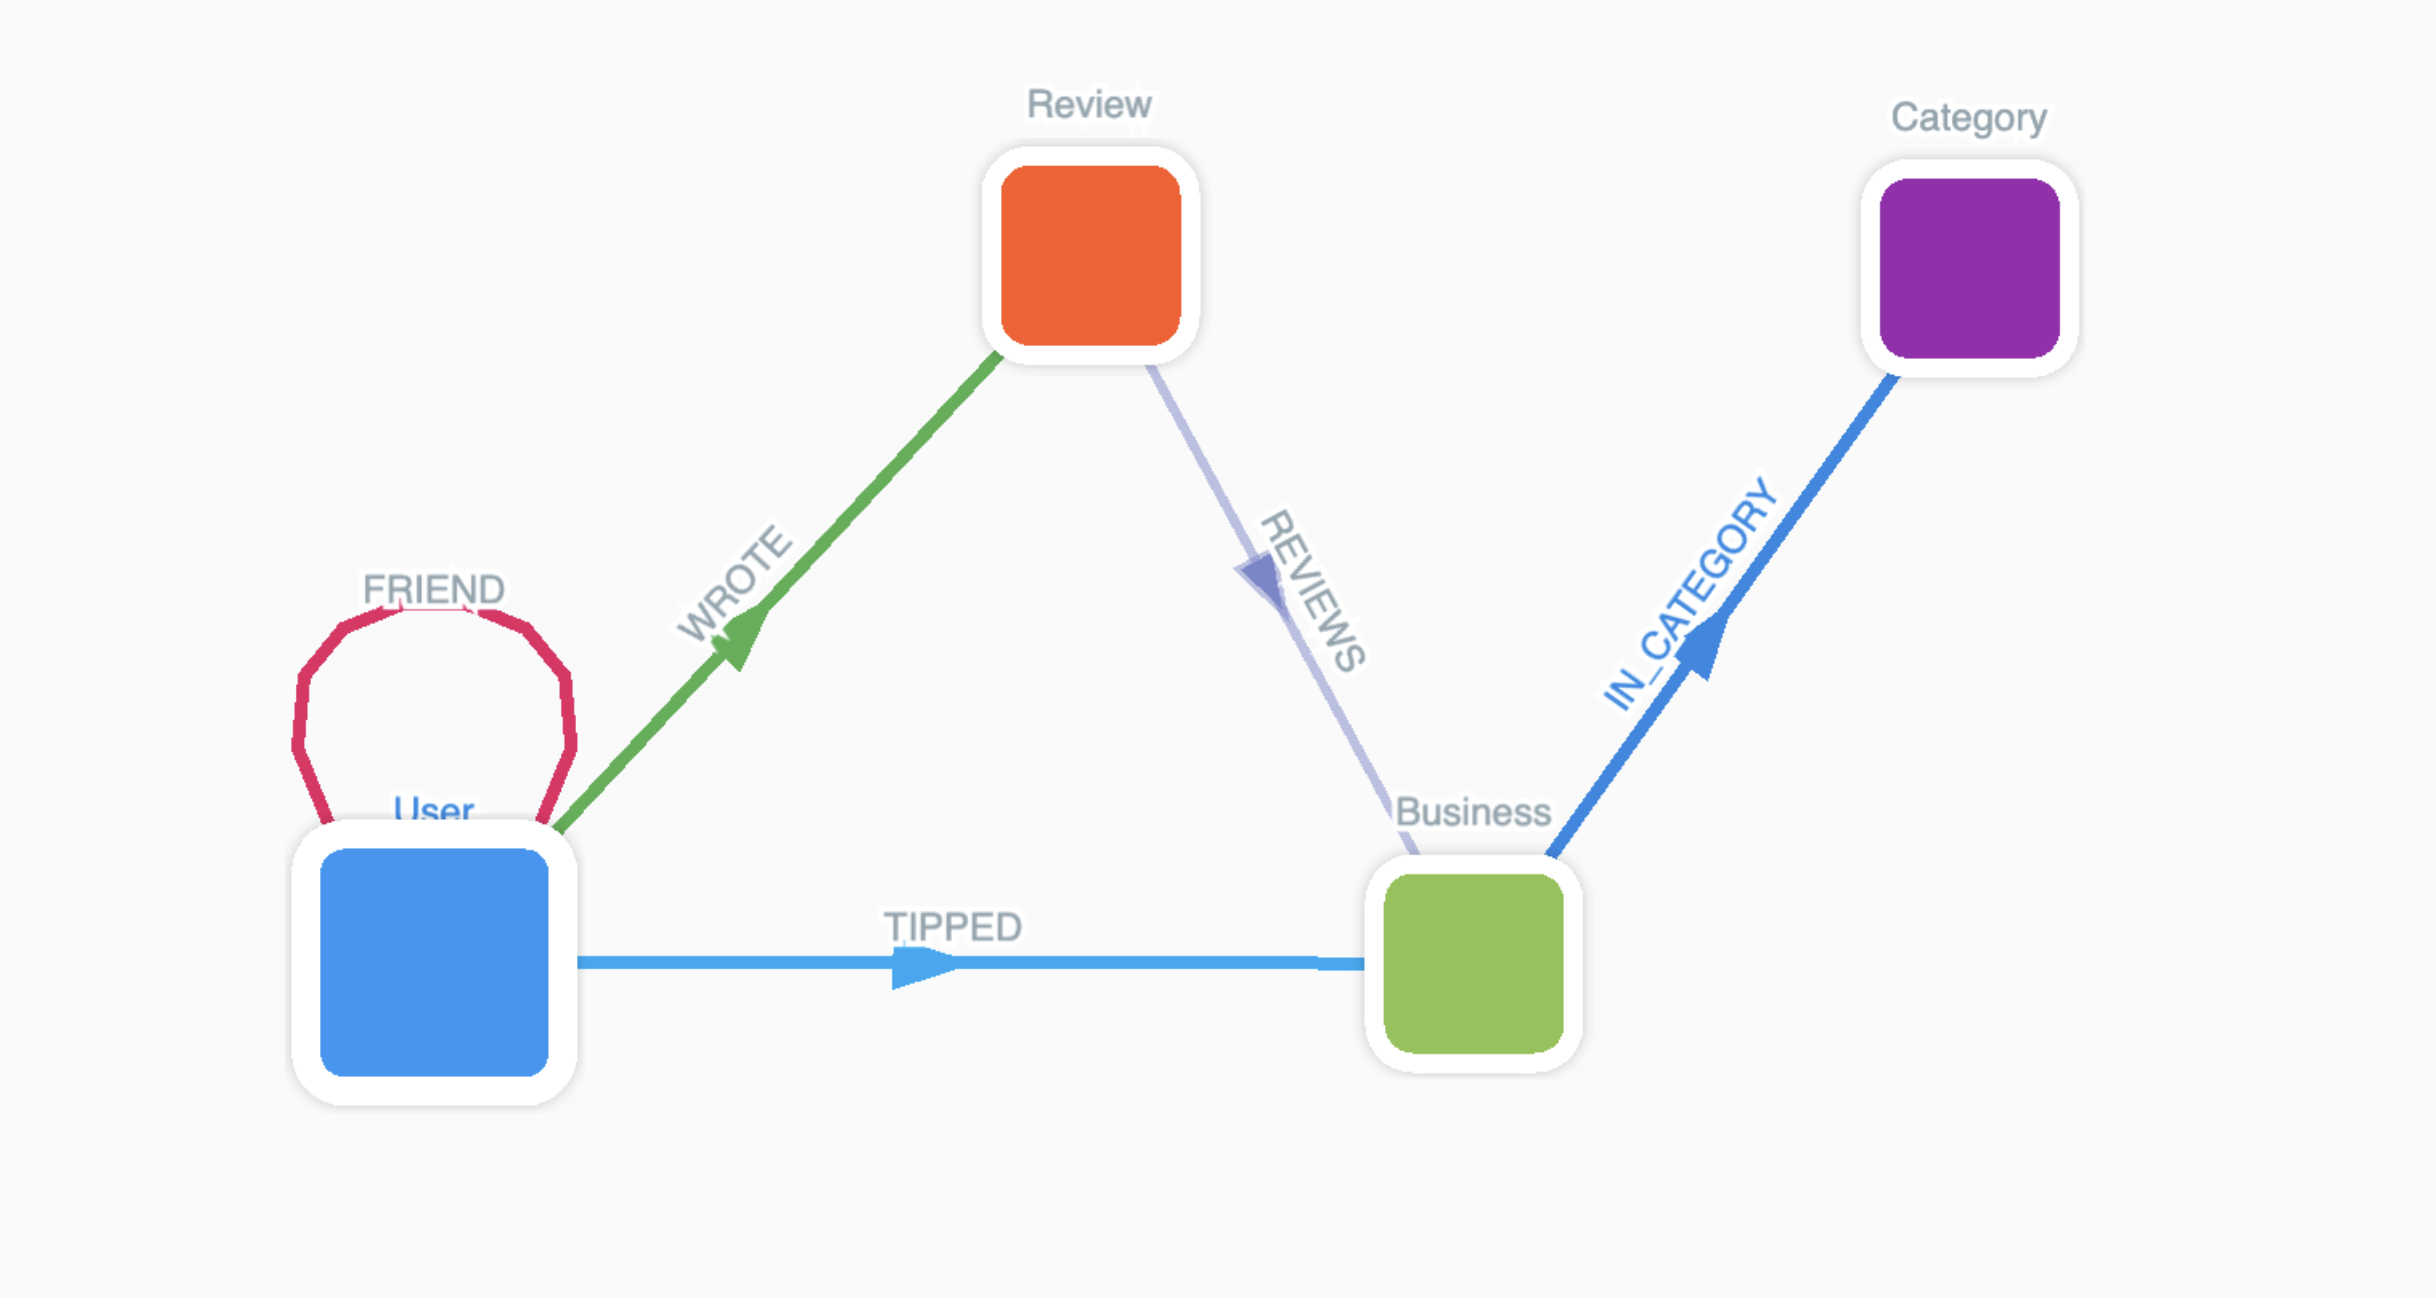
Node Statistics
| Node Label | Count |
|---|---|
| Business | 150,346 |
| Category | 1,311 |
| Review | 6,990,247 |
| User | 1,987,897 |
Edge Statistics
| Relationship | Count |
|---|---|
| (:User)-[:FRIEND]-(:User) | 14,611,748 |
| (:Business)-[:IN_CATEGORY]-(:Category) | 668,592 |
| (:Review)-[:REVIEWS]-(:Business) | 6,990,247 |
| (:User)-[:TIPPED]-(:Tip) | 908,915 |
| (:User)-[:WROTE]-(:Review) | 6,990,247 |
Data Loading
Overview
Data import is handled in four parts. First we upload all the raw data files into DataFrames. Then we define nodes and edges. Finally, we create graph schema.
DataFrames
The first thing we do would be to load all JSON files into a big DataFrame. Here we use the original JSON files downloaded from the Yelp dataset website.
Loaded business_df in 5.74 seconds, user_df in 1.47 seconds, review_df in 1.64 seconds, tip_df in 0.32 seconds
import time

# Load business dataset
start_time = time.time()
business_df = spark.read.json("hdfs://master:9000/yelp/yelp_academic_dataset_business.json")
print(f"Loaded business_df in {time.time() - start_time:.2f} seconds")

# Load user dataset
start_time = time.time()
user_df = spark.read.json("hdfs://master:9000/yelp/yelp_academic_dataset_user.json")
print(f"Loaded user_df in {time.time() - start_time:.2f} seconds")

# Load review dataset
start_time = time.time()
review_df = spark.read.json("hdfs://master:9000/yelp/yelp_academic_dataset_review.json")
print(f"Loaded review_df in {time.time() - start_time:.2f} seconds")

# Load tip dataset
start_time = time.time()
tip_df = spark.read.json("hdfs://master:9000/yelp/yelp_academic_dataset_tip.json")
print(f"Loaded tip_df in {time.time() - start_time:.2f} seconds")
Define Nodes
First we define the Business node.
business_vertices = business_df.selectExpr(
    "business_id as id",
    "'business' as type",
    "name",
    "address",
    "city",
    "state",
    "postal_code",
    "latitude",
    "longitude",
    "is_open",
    "categories",
    "stars as rating",
    "review_count"
)
Then we define the User node.
user_vertices = user_df.selectExpr(
    "user_id as id",                     # required by GraphFrames
    "'user' as type",                    # optional label for node type
    "user_id",
    "name",
    "review_count",
    "yelping_since",
    "friends",
    "useful",
    "funny",
    "cool",
    "fans",
    "elite",
    "average_stars",
    "compliment_hot",
    "compliment_more",
    "compliment_profile",
    "compliment_cute",
    "compliment_list",
    "compliment_note",
    "compliment_plain",
    "compliment_cool",
    "compliment_funny",
    "compliment_writer",
    "compliment_photos"
)
Then we define the Review node.
review_vertices = review_df.selectExpr(
    "review_id as id",           # Required by GraphFrames
    "'review' as type",          # Optional, helps distinguish node type
    "user_id",
    "business_id",
    "stars",
    "date",
    "text",
    "useful",
    "funny",
    "cool"
)
Then we define the Category node from the categories attribute of Business
node.
from pyspark.sql.functions import split, explode, trim, col, lit
exploded = business_df.filter(col("categories").isNotNull())
    .withColumn("category", explode(split("categories", ",")))
    .withColumn("category", trim(col("category")))
category_vertices = exploded
    .select("category")
    .distinct()
    .withColumnRenamed("category", "id")
    .withColumn("type", lit("category"))
Define Edges
Next step is to define edges. First we define the REVIEWED edge.
reviewed_edges = review_df.selectExpr(
    "review_id as src",
    "business_id as dst",
    "'reviews' as relationship"
)
Then we define the WROTE edge.
wrote_edges = review_df.selectExpr(
    "user_id as src",
    "review_id as dst",
    "'wrote' as relationship"
)
Then we define the TIPPED edge.
tipped_edges = tip_df.selectExpr( # tip has no id field, so just treat as edge
    "user_id as src",
    "business_id as dst",
    "'tipped' as relationship",
    "text",
    "date",
    "compliment_count"
)
Then we define the FRIENDS edge.
from pyspark.sql.functions import split, explode, col, trim
friend_edges = user_df
    .filter(col("friends").isNotNull())
    .withColumn("friend_id", explode(split(col("friends"), ", ")))
    .withColumn("friend_id", trim(col("friend_id")))
    .selectExpr("user_id as src", "friend_id as dst")
    .withColumn("relationship", lit("friend"))
Finally the IN_CATEGORY edges from Business to Category.
category_edges = exploded.selectExpr(
"business_id as src",
"trim(category) as dst",
"'in_category' as relationship"
)
Define Graph
Now that we have defined our vertices and edges, we can create graph schema with those. First, we need to union all vertex types into a single vertex dataframe, and all edge types into a single edge dataframe.
# Total columns are the union set with null value padding.
vertices = user_vertices
    .unionByName(business_vertices, allowMissingColumns=True)
    .unionByName(review_vertices, allowMissingColumns=True)
    .unionByName(category_vertices, allowMissingColumns=True)
# All edges are merged; missing columns (like tipped metadata) are padded with null.
edges = reviewed_edges
    .unionByName(wrote_edges, allowMissingColumns=True)
    .unionByName(tipped_edges, allowMissingColumns=True)
    .unionByName(category_edges, allowMissingColumns=True)
    .unionByName(friend_edges, allowMissingColumns=True)
Finally, we can create the whole graph schema.
from graphframes import GraphFrames
g = GraphFrames(vertices, edges)
Queries
Select a query below to view its logic and description.
Q1. Find the friends of all "John"s
This query retrieves the name and user ID of up to 20 friends of users named "John".
# Q1. Find the friends of all "John"s
q1 = (
    g.find("(john)-[e]->(friend)")
    .filter(
        (F.col("john.type") == "user")
        & (F.col("john.name") == "John")
        & (F.col("e.relationship") == "friend")
        & (F.col("friend.type") == "user")
    )
    .select(
        F.col("friend.name").alias("name"),
        F.col("friend.user_id").alias("user_id")
    )
    .limit(20)
)
Equivalent query in GQL standard:
MATCH (:User {name: "John"})-[:FRIEND]->(friend)
RETURN friend.name, friend.user_id
LIMIT 20
Q2. Find all users within two friend hops of a given user
This query finds all distinct users reachable within one or two FRIEND hops from a starting user.
# Q2. Find all users within two friend hops of a given user
q2_one_hop = (
    friend_graph_undirected.find("(start)-[e1]->(neighbor)")
    .filter(
        (F.col("start.user_id") == START_USER_ID)
        & (F.col("neighbor.user_id") != START_USER_ID)
    )
    .select(
        F.col("neighbor.name").alias("name"),
        F.col("neighbor.user_id").alias("user_id"),
        F.col("neighbor.review_count").alias("review_count"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q2_two_hop = (
    friend_graph_undirected.find(
        "(start)-[e1]->(middle); (middle)-[e2]->(neighbor)"
    )
    .filter(
        (F.col("start.user_id") == START_USER_ID)
        & (F.col("neighbor.user_id") != START_USER_ID)
    )
    .select(
        F.col("neighbor.name").alias("name"),
        F.col("neighbor.user_id").alias("user_id"),
        F.col("neighbor.review_count").alias("review_count"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q2 = (
    q2_one_hop
    .unionByName(q2_two_hop)
    .distinct()
    .select("name", "user_id")
    .orderBy("name", "user_id")
    .limit(100)
)
Equivalent query in GQL standard:
MATCH p = (start:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,2}(neighbor:User)
WHERE neighbor != start
RETURN DISTINCT neighbor.name AS name, neighbor.user_id AS user_id
ORDER BY name, user_id
LIMIT 100
Q3. Get 3-hop neighbors of a given user
This query identifies the unique names and user IDs of all neighbors exactly three friend-connections away from a given user.
# Q3. Get 3-hop neighbors of a given user
# Filter to the start vertex before expanding and deduplicate each frontier.
# Since the query returns distinct endpoints, this is equivalent to the
# three-edge motif without materializing every duplicate three-hop path.
q3_start_ids = (
    friend_vertices
    .filter(F.col("user_id") == START_USER_ID)
    .select(F.col("id").alias("id"))
    .distinct()
)

q3_hop1_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q3_start_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q3_hop2_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q3_hop1_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q3_hop3_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q3_hop2_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q3 = (
    friend_vertices.alias("neighbor")
    .join(
        q3_hop3_ids.alias("frontier"),
        F.col("neighbor.id") == F.col("frontier.id"),
        "inner"
    )
    .filter(F.col("neighbor.user_id") != START_USER_ID)
    .select(
        F.col("neighbor.name").alias("name"),
        F.col("neighbor.user_id").alias("user_id")
    )
    .distinct()
)
Equivalent query in GQL standard:
MATCH (start:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{3}(neighbor)
WHERE neighbor.user_id != "Oi1qbcz2m2SnwUeztGYcnQ"
RETURN DISTINCT neighbor.name, neighbor.user_id
Q4. Find high-review-count users within two friend hops
This query finds distinct users within one or two FRIEND hops of a starting user, filtered to users with at least 100 reviews and an average rating of 4.0 or higher.
# Q4. Find high-review-count users within two friend hops
q4_one_hop = (
    friend_graph_undirected.find("(start)-[e1]->(neighbor)")
    .filter(
        (F.col("start.user_id") == START_USER_ID)
        & (F.col("neighbor.user_id") != START_USER_ID)
    )
    .select(
        F.col("neighbor.name").alias("name"),
        F.col("neighbor.user_id").alias("user_id"),
        F.col("neighbor.review_count").alias("review_count"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q4_two_hop = (
    friend_graph_undirected.find(
        "(start)-[e1]->(middle); (middle)-[e2]->(neighbor)"
    )
    .filter(
        (F.col("start.user_id") == START_USER_ID)
        & (F.col("neighbor.user_id") != START_USER_ID)
    )
    .select(
        F.col("neighbor.name").alias("name"),
        F.col("neighbor.user_id").alias("user_id"),
        F.col("neighbor.review_count").alias("review_count"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q4_candidates = q4_one_hop.unionByName(q4_two_hop).distinct()

q4 = (
    q4_candidates
    .filter(
        (F.col("review_count") >= 100)
        & (F.col("average_stars") >= 4.0)
    )
    .select("name", "user_id", "review_count", "average_stars")
    .orderBy(
        F.col("review_count").desc(),
        F.col("average_stars").desc()
    )
    .limit(100)
)
Equivalent query in GQL standard:
MATCH p = (start:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,2}(neighbor:User)
WHERE neighbor != start
  AND neighbor.review_count >= 100
  AND neighbor.average_stars >= 4.0
RETURN DISTINCT neighbor.name AS name,
       neighbor.user_id AS user_id,
       neighbor.review_count AS review_count,
       neighbor.average_stars AS average_stars
ORDER BY review_count DESC, average_stars DESC
LIMIT 100
Q5. Find open, highly rated businesses in Pennsylvania
This query filters individual Business nodes by state, open status, rating, and review count without traversing edges.
# Q5. Find open, highly rated businesses in Pennsylvania
q5 = (
    g.vertices
    .filter(
        (F.col("type") == "business")
        & (F.col("state") == "PA")
        & (F.col("is_open") == 1)
        & (F.col("rating") >= 4.5)
        & (F.col("review_count") >= 100)
    )
    .select("name", "city", "rating", "review_count")
    .orderBy(
        F.col("rating").desc(),
        F.col("review_count").desc()
    )
    .limit(25)
)
Equivalent query in GQL standard:
MATCH (b:Business)
WHERE b.state = "PA"
  AND b.is_open = 1
  AND b.rating >= 4.5
  AND b.review_count >= 100
RETURN b.name, b.city, b.rating, b.review_count
ORDER BY b.rating DESC, b.review_count DESC
LIMIT 25
Q6. Find useful five-star review edges
The Yelp Neo4j schema stores review attributes on Review nodes that mediate User-to-Business edges, so this query filters those edge records by rating and usefulness.
# Q6. Find useful five-star review edges
q6 = (
    g.find("(u)-[w]->(r); (r)-[rv]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("w.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("rv.relationship") == "reviews")
        & (F.col("b.type") == "business")
        & (F.col("r.stars") == 5)
        & (F.col("r.useful") >= 10)
    )
    .select(
        F.col("u.name").alias("user_name"),
        F.col("r.id").alias("review_id"),
        F.col("r.stars").alias("stars"),
        F.col("r.useful").alias("useful_votes"),
        F.col("b.name").alias("business_name"),
        F.col("b.city").alias("city")
    )
    .orderBy(F.col("useful_votes").desc())
    .limit(20)
)
Equivalent query in GQL standard:
MATCH (u:User)-[:WROTE]->(r:Review)-[:REVIEWS]->(b:Business)
WHERE r.stars = 5
  AND r.useful >= 10
RETURN u.name AS user_name,
       r.id AS review_id,
       r.stars AS stars,
       r.useful AS useful_votes,
       b.name AS business_name,
       b.city AS city
ORDER BY useful_votes DESC
LIMIT 20
Q7. Check whether Steven can reach Niki within four friend hops
This query tests whether a bounded friend path exists between two User nodes.
# Q7. Check whether Steven can reach Niki within four friend hops
# bfs() returns a DataFrame only when a path is found. count() is the action
# that evaluates reachability.
q7_path = friend_graph_undirected.bfs(
    fromExpr=f"user_id = '{START_USER_ID}'",
    toExpr=f"user_id = '{TARGET_USER_ID}'",
    maxPathLength=4
).limit(1)

q7 = spark.createDataFrame(
    [(q7_path.count() > 0,)],
    ["reachable"]
)
Equivalent query in GQL standard:
MATCH p = ANY (source:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,4}(target:User {user_id: "WwulXySQN8t2hwqH_yWurA"})
RETURN true AS reachable
Q8. Find the shortest friend path between Steven and Niki
This query returns the shortest bounded path connecting two users in the friend graph.
# Q8. Find the shortest friend path between Steven and Niki
q8_bfs = friend_graph_undirected.bfs(
    fromExpr=f"user_id = '{START_USER_ID}'",
    toExpr=f"user_id = '{TARGET_USER_ID}'",
    maxPathLength=6
)

# GraphFrames BFS names intermediate vertex columns v1, v2, ...
q8_intermediate_vertices = sorted(
    [c for c in q8_bfs.columns if c.startswith("v")],
    key=lambda c: int(c[1:])
)
q8_vertex_columns = ["from"] + q8_intermediate_vertices + ["to"]
q8_hop_count = len([c for c in q8_bfs.columns if c.startswith("e")])

# Reciprocal FRIEND rows can produce duplicate BFS edge paths with the same
# vertex sequence. Collapse them and keep one path, matching shortestPath().
q8 = (
    q8_bfs
    .select(
        F.array(
            *[F.col(f"{c}.name") for c in q8_vertex_columns]
        ).alias("user_path"),
        F.lit(q8_hop_count).alias("hop_count")
    )
    .dropDuplicates(["user_path", "hop_count"])
    .limit(1)
)
Equivalent query in GQL standard:
MATCH p = SHORTEST (:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,6}(:User {user_id: "WwulXySQN8t2hwqH_yWurA"})
RETURN p
Q9. Enumerate simple friend paths between Steven and Niki up to length three
This query materializes acyclic friend paths up to three hops between two users.
# Q9. Enumerate simple friend paths between Steven and Niki up to length three
q9_length_1 = (
    friend_graph_undirected.find("(s)-[e1]->(t)")
    .filter(
        (F.col("s.user_id") == START_USER_ID)
        & (F.col("t.user_id") == TARGET_USER_ID)
    )
    .select(
        F.array(F.col("s.user_id"), F.col("t.user_id")).alias("user_ids"),
        F.lit(1).alias("hop_count")
    )
)

q9_length_2 = (
    friend_graph_undirected.find("(s)-[e1]->(v1); (v1)-[e2]->(t)")
    .filter(
        (F.col("s.user_id") == START_USER_ID)
        & (F.col("t.user_id") == TARGET_USER_ID)
        & (F.col("v1.id") != F.col("s.id"))
        & (F.col("v1.id") != F.col("t.id"))
    )
    .select(
        F.array(
            F.col("s.user_id"),
            F.col("v1.user_id"),
            F.col("t.user_id")
        ).alias("user_ids"),
        F.lit(2).alias("hop_count")
    )
)

q9_length_3 = (
    friend_graph_undirected.find(
        "(s)-[e1]->(v1); (v1)-[e2]->(v2); (v2)-[e3]->(t)"
    )
    .filter(
        (F.col("s.user_id") == START_USER_ID)
        & (F.col("t.user_id") == TARGET_USER_ID)
        & (F.col("v1.id") != F.col("s.id"))
        & (F.col("v1.id") != F.col("t.id"))
        & (F.col("v2.id") != F.col("s.id"))
        & (F.col("v2.id") != F.col("t.id"))
        & (F.col("v1.id") != F.col("v2.id"))
    )
    .select(
        F.array(
            F.col("s.user_id"),
            F.col("v1.user_id"),
            F.col("v2.user_id"),
            F.col("t.user_id")
        ).alias("user_ids"),
        F.lit(3).alias("hop_count")
    )
)

q9 = (
    q9_length_1
    .unionByName(q9_length_2)
    .unionByName(q9_length_3)
    .orderBy(F.col("hop_count").asc())
    .limit(20)
)
Equivalent query in GQL standard:
MATCH p = ACYCLIC (:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,3}(:User {user_id: "WwulXySQN8t2hwqH_yWurA"})
RETURN p
LIMIT 20
Q10. Find friend triangles around Steven
This query finds three-user cycles in the friend graph anchored at Steven.
# Q10. Find friend triangles around Steven
q10 = (
    friend_graph_undirected.find(
        "(a)-[e1]->(b); (b)-[e2]->(c); (c)-[e3]->(a)"
    )
    .filter(
        (F.col("a.user_id") == START_USER_ID)
        & (F.col("a.id") != F.col("b.id"))
        & (F.col("b.id") != F.col("c.id"))
        & (F.col("a.id") != F.col("c.id"))
    )
    .select(
        F.col("b.name").alias("friend_one"),
        F.col("c.name").alias("friend_two")
    )
    .distinct()
    .limit(25)
)
Equivalent query in GQL standard:
MATCH (a:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-(b:User),
      (b)-[:FRIEND]-(c:User),
      (c)-[:FRIEND]-(a)
WHERE a <> b AND b <> c AND a <> c
RETURN DISTINCT b.name AS friend_one, c.name AS friend_two
LIMIT 25
Q11. Find friend squares around Steven
This query searches for four-user cycles that include Steven.
# Q11. Find friend squares around Steven
q11 = (
    friend_graph_undirected.find(
        "(a)-[e1]->(b); "
        "(b)-[e2]->(c); "
        "(c)-[e3]->(d); "
        "(d)-[e4]->(a)"
    )
    .filter(
        (F.col("a.user_id") == START_USER_ID)
        & (F.col("a.id") != F.col("b.id"))
        & (F.col("a.id") != F.col("c.id"))
        & (F.col("a.id") != F.col("d.id"))
        & (F.col("b.id") != F.col("c.id"))
        & (F.col("b.id") != F.col("d.id"))
        & (F.col("c.id") != F.col("d.id"))
    )
    .select(
        F.col("b.name").alias("first_friend"),
        F.col("c.name").alias("bridge_friend"),
        F.col("d.name").alias("second_friend")
    )
    .distinct()
    .limit(25)
)
Equivalent query in GQL standard:
MATCH (a:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-(b:User),
      (b)-[:FRIEND]-(c:User),
      (c)-[:FRIEND]-(d:User),
      (d)-[:FRIEND]-(a)
WHERE a <> b AND a <> c AND a <> d
  AND b <> c AND b <> d AND c <> d
RETURN DISTINCT b.name AS first_friend, c.name AS bridge_friend, d.name AS second_friend
LIMIT 25
Q12. Find high-review-count friend stars
This query finds users who are connected to many prolific reviewer friends.
# Q12. Find high-review-count friend stars
q12 = (
    g.find("(center)-[e]->(friend)")
    .filter(
        (F.col("center.type") == "user")
        & (F.col("e.relationship") == "friend")
        & (F.col("friend.type") == "user")
        & (F.col("friend.review_count") >= 100)
    )
    .groupBy(
        F.col("center.name").alias("center_name"),
        F.col("center.user_id").alias("center_id")
    )
    .agg(F.count("*").alias("prolific_friend_count"))
    .orderBy(F.col("prolific_friend_count").desc())
    .limit(25)
)
Equivalent query in GQL standard:
MATCH (center:User)-[:FRIEND]->(friend:User)
WHERE friend.review_count >= 100
RETURN center.name AS center_name,
       center.user_id AS center_id,
       count(friend) AS prolific_friend_count
ORDER BY prolific_friend_count DESC
LIMIT 25
Q13. Find four-user cliques around Steven
This query finds fully connected groups of four users containing Steven.
# Q13. Find four-user cliques around the given user
#
# Do not express all six clique edges as one motif over the full friend graph.
# GraphFrames can enumerate the global four-clique intermediate before pushing
# the predicate on a.user_id, producing tens of billions of shuffle records.
# First restrict the graph to the start user's neighbors. A four-clique that
# contains the start user is then exactly a triangle in this induced subgraph.
q13_start_ids = (
    friend_vertices
    .filter(F.col("user_id") == START_USER_ID)
    .select(F.col("id").alias("start_id"))
)

q13_neighbor_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q13_start_ids.alias("start"),
        F.col("edge.src") == F.col("start.start_id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q13_neighbor_vertices = (
    friend_vertices
    .join(q13_neighbor_ids, "id", "inner")
)

q13_neighbor_edges = (
    friend_edges_undirected.alias("edge")
    .join(
        q13_neighbor_ids.select(F.col("id").alias("neighbor_src")),
        F.col("edge.src") == F.col("neighbor_src"),
        "inner"
    )
    .join(
        q13_neighbor_ids.select(F.col("id").alias("neighbor_dst")),
        F.col("edge.dst") == F.col("neighbor_dst"),
        "inner"
    )
    .select(
        F.col("edge.src").alias("src"),
        F.col("edge.dst").alias("dst"),
        F.col("edge.relationship").alias("relationship")
    )
    # Multiple stored/reversed FRIEND rows do not change clique existence.
    .dropDuplicates(["src", "dst"])
)

q13_neighbor_graph = GraphFrame(q13_neighbor_vertices, q13_neighbor_edges)

q13 = (
    q13_neighbor_graph.find(
        "(b)-[bc]->(c); "
        "(b)-[bd]->(d); "
        "(c)-[cd]->(d)"
    )
    .filter(
        (F.col("b.user_id") < F.col("c.user_id"))
        & (F.col("c.user_id") < F.col("d.user_id"))
    )
    .select(
        F.col("b.name").alias("user_b"),
        F.col("c.name").alias("user_c"),
        F.col("d.name").alias("user_d")
    )
    .limit(10)
)
Equivalent query in GQL standard:
MATCH (a:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-(b:User),
      (a)-[:FRIEND]-(c:User),
      (a)-[:FRIEND]-(d:User),
      (b)-[:FRIEND]-(c),
      (b)-[:FRIEND]-(d),
      (c)-[:FRIEND]-(d)
WHERE b.user_id < c.user_id AND c.user_id < d.user_id
RETURN b.name AS user_b, c.name AS user_c, d.name AS user_d
LIMIT 10
Q14. Find mutual friends between Steven and Niki
This query finds the names and user IDs of all mutual friends between two specific users, Steven and Niki.
# Q14. Find mutual friends between Steven and Niki
q14 = (
    g.find("(a)-[e1]->(mutual); (b)-[e2]->(mutual)")
    .filter(
        (F.col("a.type") == "user")
        & (F.col("a.user_id") == START_USER_ID)
        & (F.col("e1.relationship") == "friend")
        & (F.col("b.type") == "user")
        & (F.col("b.user_id") == TARGET_USER_ID)
        & (F.col("e2.relationship") == "friend")
        & (F.col("mutual.type") == "user")
    )
    .select(
        F.col("mutual.name").alias("name"),
        F.col("mutual.user_id").alias("user_id")
    )
    .distinct()
)
Equivalent query in GQL standard:
MATCH (a:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]->(mutual)<-[:FRIEND]-(b:User {user_id: "WwulXySQN8t2hwqH_yWurA"})
RETURN DISTINCT mutual.name, mutual.user_id
Q15. For a given user's friends, find their reviewed businesses along with locations
This query lists the businesses, including their physical addresses and coordinates, that have been reviewed by a given user's friends.
# Q15. For a given user's friends, find their reviewed businesses and locations
q15 = (
    g.find(
        "(u)-[friend_edge]->(friend); "
        "(friend)-[wrote_edge]->(r); "
        "(r)-[review_edge]->(b)"
    )
    .filter(
        (F.col("u.type") == "user")
        & (F.col("u.user_id") == START_USER_ID)
        & (F.col("friend_edge.relationship") == "friend")
        & (F.col("friend.type") == "user")
        & (F.col("wrote_edge.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("review_edge.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .select(
        F.col("friend.name").alias("friend_name"),
        F.col("b.name").alias("business_name"),
        F.col("b.address").alias("address"),
        F.col("b.city").alias("city"),
        F.col("b.state").alias("state"),
        F.col("b.latitude").alias("latitude"),
        F.col("b.longitude").alias("longitude")
    )
    .distinct()
    .orderBy("friend_name", "business_name")
)
Equivalent query in GQL standard:
MATCH (u:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]->(friend:User)-[:WROTE]->(r:Review)-[:REVIEWS]->(b:Business)
RETURN DISTINCT friend.name AS friend_name,
b.name AS business_name,
b.address, b.city, b.state,
b.latitude, b.longitude
ORDER BY friend_name, business_name
Q16. Count the friends of all "John"s
This query calculates the total number of unique friends belonging to all users named "John".
# Q16. Count the friends of all "John"s
q16 = (
    g.find("(john)-[e]->(friend)")
    .filter(
        (F.col("john.type") == "user")
        & (F.col("john.name") == "John")
        & (F.col("e.relationship") == "friend")
        & (F.col("friend.type") == "user")
    )
    .agg(F.countDistinct("friend.id").alias("total_friends"))
)
Equivalent query in GQL standard:
MATCH (:User {name: "John"})-[:FRIEND]->(friend)
RETURN count(DISTINCT friend) AS total_friends
Q17. Find businesses with only negative reviews
This query finds businesses where every review rating is less than 3 stars, ordered by the volume of reviews.
# Q17. Find businesses with only negative reviews
q17 = (
    g.find("(r)-[e]->(b)")
    .filter(
        (F.col("r.type") == "review")
        & (F.col("e.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .groupBy(
        F.col("b.id").alias("business_id"),
        F.col("b.name").alias("business_name")
    )
    .agg(F.collect_list("r.stars").alias("stars"))
    .filter(F.array_max("stars") < 3)
    .select("business_name", "stars")
    .orderBy(F.size("stars").desc())
)
Equivalent query in GQL standard:
MATCH (b:Business)<-[:REVIEWS]-(r:Review)
RETURN b.name, collect(r.stars) AS stars
  WHERE ALL(star IN stars WHERE star < 3)
ORDER BY size(stars) DESC
Q18. Summarize review-edge counts and ratings
The Yelp schema stores review rating on Review nodes rather than relationship properties, so this query summarizes the review-mediated User-to-Business edges.
# Q18. Summarize review-edge counts and ratings
q18 = (
    g.find("(u)-[w]->(r); (r)-[rv]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("w.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("rv.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .agg(
        F.count("*").alias("review_edge_count"),
        F.avg("r.stars").alias("avg_review_stars"),
        F.min("r.stars").alias("min_review_stars"),
        F.max("r.stars").alias("max_review_stars")
    )
)
Equivalent query in GQL standard:
MATCH (:User)-[:WROTE]->(r:Review)-[:REVIEWS]->(:Business)
RETURN count(r) AS review_edge_count,
       avg(r.stars) AS avg_review_stars,
       min(r.stars) AS min_review_stars,
       max(r.stars) AS max_review_stars
Q19. Summarize review ratings by business state
This query groups review-mediated User-to-Business edges by the destination business state and summarizes ratings.
# Q19. Summarize review ratings by business state
q19 = (
    g.find("(u)-[w]->(r); (r)-[rv]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("w.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("rv.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .groupBy(F.col("b.state").alias("state"))
    .agg(
        F.count("*").alias("review_edge_count"),
        F.avg("r.stars").alias("avg_review_stars"),
        F.min("r.stars").alias("min_review_stars"),
        F.max("r.stars").alias("max_review_stars")
    )
    .orderBy(F.col("review_edge_count").desc())
    .limit(25)
)
Equivalent query in GQL standard:
MATCH (:User)-[:WROTE]->(r:Review)-[:REVIEWS]->(b:Business)
RETURN b.state AS state,
       count(r) AS review_edge_count,
       avg(r.stars) AS avg_review_stars,
       min(r.stars) AS min_review_stars,
       max(r.stars) AS max_review_stars
ORDER BY review_edge_count DESC
LIMIT 25
Q20. Count Steven's friend paths by length
This query counts all bounded friend paths from Steven and groups them by hop length.
# Q20. Count Steven's friend paths by length
# FRIEND rows are already reciprocal in the stored table. Use friend_graph
# directly so adding a reversed copy does not double every hop.
q20_paths_1 = (
    friend_graph.find("(s)-[e1]->(neighbor)")
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(1).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q20_paths_2 = (
    friend_graph.find("(s)-[e1]->(v1); (v1)-[e2]->(neighbor)")
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(2).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q20_paths_3 = (
    friend_graph.find(
        "(s)-[e1]->(v1); (v1)-[e2]->(v2); (v2)-[e3]->(neighbor)"
    )
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(3).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q20_all_paths = (
    q20_paths_1
    .unionByName(q20_paths_2)
    .unionByName(q20_paths_3)
)


q20 = (
    q20_all_paths
    .groupBy("path_length")
    .agg(
        F.count("*").alias("path_count"),
        F.countDistinct("neighbor_id").alias("distinct_neighbor_count")
    )
    .orderBy(F.col("path_length").asc())
)
Equivalent query in GQL standard:
MATCH p = (:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,3}(neighbor:User)
RETURN length(p) AS path_length,
       count(p) AS path_count,
       count(DISTINCT neighbor) AS distinct_neighbor_count
ORDER BY path_length ASC
Q21. Count Steven's friend paths by length and rating bucket
This query extends Q20 by grouping endpoint users into average-star buckets.
# Q21. Count Steven's friend paths by length and rating bucket
# As in Q20, the stored reciprocal FRIEND rows already support traversal in
# either logical direction; do not add another reversed edge copy.
q21_paths_1 = (
    friend_graph.find("(s)-[e1]->(neighbor)")
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(1).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q21_paths_2 = (
    friend_graph.find("(s)-[e1]->(v1); (v1)-[e2]->(neighbor)")
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(2).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q21_paths_3 = (
    friend_graph.find(
        "(s)-[e1]->(v1); (v1)-[e2]->(v2); (v2)-[e3]->(neighbor)"
    )
    .filter(F.col("s.user_id") == START_USER_ID)
    .select(
        F.lit(3).alias("path_length"),
        F.col("neighbor.user_id").alias("neighbor_id"),
        F.col("neighbor.average_stars").alias("average_stars")
    )
)

q21_all_paths = (
    q21_paths_1
    .unionByName(q21_paths_2)
    .unionByName(q21_paths_3)
)

q21 = (
    q21_all_paths
    .withColumn(
        "rating_bucket",
        F.when(F.col("average_stars") >= 4.0, "high")
        .when(F.col("average_stars") >= 3.0, "medium")
        .otherwise("low")
    )
    .groupBy("path_length", "rating_bucket")
    .agg(
        F.count("*").alias("path_count"),
        F.countDistinct("neighbor_id").alias("distinct_neighbor_count")
    )
    .orderBy(
        F.col("path_length").asc(),
        F.col("path_count").desc()
    )
    .limit(25)
)
Equivalent query in GQL standard:
MATCH p = (:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{1,3}(neighbor:User)
WITH p, neighbor,
     CASE
       WHEN neighbor.average_stars >= 4.0 THEN "high"
       WHEN neighbor.average_stars >= 3.0 THEN "medium"
       ELSE "low"
     END AS rating_bucket
RETURN length(p) AS path_length,
       rating_bucket,
       count(p) AS path_count,
       count(DISTINCT neighbor) AS distinct_neighbor_count
ORDER BY path_length ASC, path_count DESC
LIMIT 25
Q22. Find the total number of reviews and tips for each business
This query calculates the combined count of reviews and tips for every business, sorting them in descending order of total user interactions.
# Q22. Find the total number of reviews and tips for each business
q22_businesses = (
    g.vertices
    .filter(F.col("type") == "business")
    .select(
        F.col("id").alias("business_id"),
        F.col("name").alias("business_name")
    )
)

q22_review_counts = (
    g.find("(r)-[e]->(b)")
    .filter(
        (F.col("r.type") == "review")
        & (F.col("e.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .select(
        F.col("b.id").alias("business_id"),
        F.col("r.id").alias("review_id")
    )
    .groupBy("business_id")
    .agg(F.countDistinct("review_id").alias("num_reviews"))
)

# A tip is an edge in this GraphFrames schema, not a Tip vertex. Each motif row
# is one TIPPED edge, so count rows without collapsing user-business pairs.
q22_tip_counts = (
    g.find("(u)-[t]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("t.relationship") == "tipped")
        & (F.col("b.type") == "business")
    )
    .select(F.col("b.id").alias("business_id"))
    .groupBy("business_id")
    .agg(F.count("*").alias("num_tips"))
)


# The two joins implement Cypher OPTIONAL MATCH; GraphFrames motifs have no
# optional-edge syntax.
q22 = (
    q22_businesses
    .join(q22_review_counts, on="business_id", how="left")
    .join(q22_tip_counts, on="business_id", how="left")
    .fillna({"num_reviews": 0, "num_tips": 0})
    .withColumn("total", F.col("num_reviews") + F.col("num_tips"))
    .select("business_name", "num_reviews", "num_tips", "total")
    .orderBy(F.col("total").desc())
)
Equivalent query in GQL standard:
MATCH (b:Business)
OPTIONAL MATCH (b)<-[:REVIEWS]-(r:Review)
OPTIONAL MATCH (b)<-[:TIPPED]-(t:Tip)
RETURN b.name AS business_name,
       count(DISTINCT r) AS num_reviews,
       count(DISTINCT t) AS num_tips,
       (count(DISTINCT r) + count(DISTINCT t)) AS total
ORDER BY total DESC
Q23. Find the businesses with both tips and reviews, and return their counts
This query finds businesses that have received both reviews and tips, returning the counts of each along with their combined total.
# Q23. Find businesses with both tips and reviews and return their counts
q23_businesses = (
    g.vertices
    .filter(F.col("type") == "business")
    .select(
        F.col("id").alias("business_id"),
        F.col("name").alias("business_name")
    )
)

q23_review_counts = (
    g.find("(r)-[e]->(b)")
    .filter(
        (F.col("r.type") == "review")
        & (F.col("e.relationship") == "reviews")
        & (F.col("b.type") == "business")
    )
    .select(
        F.col("b.id").alias("business_id"),
        F.col("r.id").alias("review_id")
    )
    .groupBy("business_id")
    .agg(F.countDistinct("review_id").alias("num_reviews"))
)

q23_tip_counts = (
    g.find("(u)-[t]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("t.relationship") == "tipped")
        & (F.col("b.type") == "business")
    )
    .select(F.col("b.id").alias("business_id"))
    .groupBy("business_id")
    .agg(F.count("*").alias("num_tips"))
)

q23 = (
    q23_businesses
    .join(q23_review_counts, on="business_id", how="inner")
    .join(q23_tip_counts, on="business_id", how="inner")
    .withColumn("total", F.col("num_reviews") + F.col("num_tips"))
    .select("business_name", "num_reviews", "num_tips", "total")
    .orderBy(F.col("total").desc())
)
Equivalent query in GQL standard:
MATCH (b:Business)<-[:REVIEWS]-(r:Review)
MATCH (b)<-[:TIPPED]-(t:Tip)
RETURN b.name AS business_name,
       count(DISTINCT r) AS num_reviews,
       count(DISTINCT t) AS num_tips,
       (count(DISTINCT r) + count(DISTINCT t)) AS total
ORDER BY total DESC
Q24. Print all the text reviews and tips for a specific restaurant
This query compiles all text content from reviews and tips written for a specific restaurant named "Acme Oyster House".
# Q24. Print all text reviews and tips for a specific restaurant
q24_reviews = (
    g.find("(r)-[e]->(b)")
    .filter(
        (F.col("r.type") == "review")
        & (F.col("e.relationship") == "reviews")
        & (F.col("b.type") == "business")
        & (F.col("b.name") == "Acme Oyster House")
    )
    .select(
        F.col("b.id").alias("business_id"),
        F.col("r.text").alias("text"),
        F.lit("review").alias("type")
    )
)

q24_tips = (
    g.find("(u)-[t]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("t.relationship") == "tipped")
        & (F.col("b.type") == "business")
        & (F.col("b.name") == "Acme Oyster House")
    )
    .select(
        F.col("b.id").alias("business_id"),
        F.col("t.text").alias("text"),
        F.lit("tip").alias("type")
    )
)

q24 = q24_reviews.unionByName(q24_tips).distinct()
Equivalent query in GQL standard:
MATCH (b:Business {name: "Acme Oyster House"})
MATCH (b)<-[:REVIEWS]-(r:Review)
RETURN b.id AS business_id, r.text AS text, 'review' AS type
UNION
MATCH (b:Business {name: "Acme Oyster House"})
MATCH (b)<-[:TIPPED]-(t:Tip)
RETURN b.id AS business_id, t.text AS text, 'tip' AS type
Q25. Run degree centrality on the in-memory friend-graph and write the results back to the database
This query runs the Degree Centrality algorithm on the friend graph to count each user's direct connections and stores the centrality score.
The queries in the Analytics category would require projecting a in-memory GDS graph first. Run the below query to do it.
# Q25. Run degree centrality on the friend graph
# GraphFrames degrees = in-degree + out-degree.
q25 = (
    friend_graph.vertices
    .join(friend_graph.degrees, on="id", how="left")
    .fillna({"degree": 0})
    .select("name", "user_id", "degree")
    .orderBy(F.col("degree").desc())
    .limit(10)
)
Then run the following analytic query.
Q26. Run page rank on the in-memory friend-graph and write the results back to the database
This query runs the PageRank algorithm on the friend graph to measure user influence and lists the top 10 most influential users.
The queries in the Analytics category would require projecting a in-memory GDS graph first. Run the below query to do it.
# Q26. Run PageRank on the undirected in-memory friend graph projected by Q25
q26_pagerank_graph = friend_graph_undirected.pageRank(
    resetProbability=0.15,
    maxIter=20
)

q26 = (
    q26_pagerank_graph.vertices
    .select("name", "user_id", "pagerank")
    .orderBy(F.col("pagerank").desc())
    .limit(10)
)
Then run the following analytic query.
Q27. Find weakly connected components (WCC) and query the size of each WCC
This query groups users into weakly connected components based on mutual or directional friendships and lists the sizes of the largest components.
The queries in the Analytics category would require projecting a in-memory GDS graph first. Run the below query to do it.
# Q27. Find weakly connected components and their sizes
# A checkpoint directory must be configured before running this query.
spark.sparkContext.setCheckpointDir(
    "hdfs://master:9000/tmp/spark-checkpoints"
)

q27_components = friend_graph.connectedComponents()

q27 = (
    q27_components
    .groupBy("component")
    .agg(F.count("*").alias("component_size"))
    .select(
        F.col("component").alias("componentId"),
        "component_size"
    )
    .orderBy(F.col("component_size").desc())
    .limit(10)
)
Then run the following analytic query.
Q28. Find strongly connected components in the directed friend graph
This query runs strongly connected components on the directed FRIEND graph and reports the largest components.
The queries in the Analytics category would require projecting a in-memory GDS graph first. Run the below query to do it.
# Q28. Find strongly connected components in the directed friend graph
q28_components = friend_graph.stronglyConnectedComponents(maxIter=20)

q28 = (
    q28_components
    .groupBy("component")
    .agg(F.count("*").alias("component_size"))
    .select(
        F.col("component").alias("componentId"),
        "component_size"
    )
    .orderBy(F.col("component_size").desc())
    .limit(20)
)
Then run the following analytic query.
Q29. Find Louvain Community and query the size of each community
This query identifies community structures within the user friendship network using the Louvain modularity optimization algorithm and lists the largest communities.
The queries in the Analytics category would require projecting a in-memory GDS graph first. Run the below query to do it.
# Q29. Find Louvain communities and their sizes
# There is no Louvain implementation in core GraphFrames. The following uses
# label propagation, which is a different community-detection algorithm and
# must not be reported as a Louvain result. Use an external Spark Louvain
# implementation if exact algorithm parity with Neo4j GDS is required.
q29 = None  # Exact translation unavailable in core GraphFrames.

q29_label_propagation_vertices = friend_graph.labelPropagation(maxIter=20)

q29_label_propagation = (
    q29_label_propagation_vertices
    .groupBy("label")
    .agg(F.count("*").alias("size"))
    .select(F.col("label").alias("communityId"), "size")
    .orderBy(F.col("size").desc())
    .limit(10)
)
Then run the following analytic query.
Q30. Count 3-hop neighbors of a given user
This query calculates the total number of unique users who are exactly three friend-connections away from a given user.
# Q30. Count three-hop neighbors of a given user
q30_start_ids = (
    friend_vertices
    .filter(F.col("user_id") == START_USER_ID)
    .select(F.col("id").alias("id"))
    .distinct()
)

q30_hop1_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q30_start_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q30_hop2_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q30_hop1_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q30_hop3_ids = (
    friend_edges_undirected.alias("edge")
    .join(
        q30_hop2_ids.alias("frontier"),
        F.col("edge.src") == F.col("frontier.id"),
        "inner"
    )
    .select(F.col("edge.dst").alias("id"))
    .distinct()
)

q30_neighbors = (
    friend_vertices.alias("neighbor")
    .join(
        q30_hop3_ids.alias("frontier"),
        F.col("neighbor.id") == F.col("frontier.id"),
        "inner"
    )
    .filter(F.col("neighbor.user_id") != START_USER_ID)
    .select(F.col("neighbor.user_id").alias("user_id"))
    .distinct()
)

q30 = q30_neighbors.agg(
    F.countDistinct("user_id").alias("three_hop_count")
)
Equivalent query in GQL standard:
MATCH (start:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]-{3}(neighbor)
WHERE neighbor.user_id != "Oi1qbcz2m2SnwUeztGYcnQ"
RETURN count(DISTINCT neighbor) AS three_hop_count
Q31. Who has the most mutual friends with a given user
This query finds the top 50 users who share the highest number of mutual friends with a given user.
# Q31. Who has the most mutual friends with a given user
q31 = (
    g.find("(me)-[r1]->(f); (other)-[r2]->(f)")
    .filter(
        (F.col("me.type") == "user")
        & (F.col("me.user_id") == START_USER_ID)
        & (F.col("r1.relationship") == "friend")
        & (F.col("f.type") == "user")
        & (F.col("other.type") == "user")
        & (F.col("r2.relationship") == "friend")
        & (F.col("other.id") != F.col("me.id"))
    )
    .groupBy(
        F.col("other.user_id").alias("user_id"),
        F.col("other.name").alias("name")
    )
    .agg(F.countDistinct(F.col("f.user_id")).alias("mutual_count"))
    .select("user_id", "name", "mutual_count")
    .orderBy(F.col("mutual_count").desc(), F.col("user_id").asc())
    .limit(50)
)
Equivalent query in GQL standard:
MATCH (me:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]->(f:User)
MATCH (other:User)-[:FRIEND]->(f)
WHERE other != me
RETURN other.name, count(f) AS mutual_count
ORDER BY mutual_count DESC
LIMIT 50
Q32. For a given user's friends, count the friend-business pairs
This query counts the total number of distinct friend-business review relationships among the friends of a given user.
# Q32. For a given user's friends, count friend-business pairs
q32 = (
    g.find(
        "(u)-[friend_edge]->(friend); "
        "(friend)-[wrote_edge]->(r); "
        "(r)-[review_edge]->(business)"
    )
    .filter(
        (F.col("u.type") == "user")
        & (F.col("u.user_id") == START_USER_ID)
        & (F.col("friend_edge.relationship") == "friend")
        & (F.col("friend.type") == "user")
        & (F.col("wrote_edge.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("review_edge.relationship") == "reviews")
        & (F.col("business.type") == "business")
    )
    .select(
        F.col("friend.user_id").alias("friend_id"),
        F.col("business.id").alias("business_id"),
    )
    .distinct()
    .agg(F.count("*").alias("total_results"))
)
Equivalent query in GQL standard:
CALL {
  MATCH (u:User {user_id: "Oi1qbcz2m2SnwUeztGYcnQ"})-[:FRIEND]->(friend:User)-[:WROTE]->(r:Review)-[:REVIEWS]->(b:Business)
  RETURN DISTINCT
    friend.name AS friend_name,
    b.name AS business_name,
    b.address AS address,
    b.city AS city,
    b.state AS state,
    b.latitude AS latitude,
    b.longitude AS longitude
}
RETURN count(*) AS total_results
Q33. Find all users who commented on the above businesses
This query lists all unique users who have written reviews for businesses situated within a 5-mile radius of a specific coordinate.
The following query requires a new attribute on Business nodes be set. Run this query to set
location on Business nodes.
# Q33. Find all users who commented on businesses within five miles
# Shared great-circle distance expression is also reused by Q35, Q37, and Q38.
EARTH_RADIUS_METERS = 6_371_000.0
CENTER_LATITUDE = 39.877788
CENTER_LONGITUDE = -75.69293535784999
FIVE_MILES_METERS = 8046.72


def haversine_meters(latitude_column, longitude_column):
    center_lat = F.radians(F.lit(CENTER_LATITUDE))
    center_lon = F.radians(F.lit(CENTER_LONGITUDE))
    latitude = F.radians(latitude_column.cast("double"))
    longitude = F.radians(longitude_column.cast("double"))
    delta_lat = latitude - center_lat
    delta_lon = longitude - center_lon
    haversine_a = (
        F.pow(F.sin(delta_lat / 2.0), 2)
        + F.cos(center_lat)
        * F.cos(latitude)
        * F.pow(F.sin(delta_lon / 2.0), 2)
    )
    return (
        F.lit(2.0 * EARTH_RADIUS_METERS)
        * F.atan2(
            F.sqrt(haversine_a),
            F.sqrt(F.lit(1.0) - haversine_a)
        )
    )


q33_pattern = (
    g.find("(u)-[w]->(r); (r)-[rv]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("w.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("rv.relationship") == "reviews")
        & (F.col("b.type") == "business")
        & F.col("b.latitude").isNotNull()
        & F.col("b.longitude").isNotNull()
    )
    .select(
        F.col("u.user_id").alias("user_id"),
        F.col("u.name").alias("name"),
        F.col("b.latitude").alias("latitude"),
        F.col("b.longitude").alias("longitude")
    )
    .withColumn(
        "dist_meters",
        haversine_meters(F.col("latitude"), F.col("longitude"))
    )
    .filter(F.col("dist_meters") <= FIVE_MILES_METERS)
)

q33 = (
    q33_pattern
    .select("user_id", "name")
    .distinct()
    .orderBy("name")
)
Then we build point index with the location values.
Q34. Find the median of the above locations (from Q15)
This query calculates the median latitude and longitude of all businesses reviewed by the friends of a given user.
# Q34. Find the median of business locations reached by the Q15 pattern
q34_locations = (
    g.find(
        "(u)-[friend_edge]->(friend); "
        "(friend)-[wrote_edge]->(r); "
        "(r)-[review_edge]->(b)"
    )
    .filter(
        (F.col("u.type") == "user")
        & (F.col("u.user_id") == START_USER_ID)
        & (F.col("friend_edge.relationship") == "friend")
        & (F.col("friend.type") == "user")
        & (F.col("wrote_edge.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("review_edge.relationship") == "reviews")
        & (F.col("b.type") == "business")
        & F.col("b.latitude").isNotNull()
        & F.col("b.longitude").isNotNull()
    )
    .select(
        F.col("b.id").alias("business_id"),
        F.col("b.latitude").alias("latitude"),
        F.col("b.longitude").alias("longitude")
    )
    .distinct()
)

# percentile_cont is the exact continuous percentile equivalent of Neo4j's
# percentileCont. It is available in current Spark SQL releases.
q34 = q34_locations.agg(
    F.expr(
        "percentile_cont(0.5) WITHIN GROUP (ORDER BY latitude)"
    ).alias("median_latitude"),
    F.expr(
        "percentile_cont(0.5) WITHIN GROUP (ORDER BY longitude)"
    ).alias("median_longitude")
)
percentileCont
is a non-standard aggregate function not supported by standard GQL.
Q35. Count the number of users who commented on the above businesses
This query calculates the total number of unique users who have reviewed businesses within a 5-mile radius of a specific coordinate.
The following query requires a new attribute on Business nodes be set. Run this query to set
location on Business nodes.
# Q35. Count users who commented on businesses within five miles
q35_pattern = (
    g.find("(u)-[w]->(r); (r)-[rv]->(b)")
    .filter(
        (F.col("u.type") == "user")
        & (F.col("w.relationship") == "wrote")
        & (F.col("r.type") == "review")
        & (F.col("rv.relationship") == "reviews")
        & (F.col("b.type") == "business")
        & F.col("b.latitude").isNotNull()
        & F.col("b.longitude").isNotNull()
    )
    .select(
        F.col("u.user_id").alias("user_id"),
        F.col("b.latitude").alias("latitude"),
        F.col("b.longitude").alias("longitude")
    )
    .withColumn(
        "dist_meters",
        haversine_meters(F.col("latitude"), F.col("longitude"))
    )
    .filter(F.col("dist_meters") <= FIVE_MILES_METERS)
)

q35 = q35_pattern.agg(
    F.countDistinct("user_id").alias("user_count")
)
Then we build point index with the location values.
Q36. Find the most frequent names
This query counts the occurrences of each user name in the dataset and returns the top 30 most frequent names in descending order.
# Q36. Find the most frequent user names
q36 = (
    g.vertices
    .filter(F.col("type") == "user")
    .groupBy("name")
    .agg(F.count("*").alias("occurrences"))
    .orderBy(F.col("occurrences").desc())
    .limit(30)
)
Equivalent query in GQL standard:
MATCH (u:User)
RETURN u.name AS name, count(*) AS occurrences
ORDER BY occurrences DESC
LIMIT 30
Q37. Find all businesses within 5 miles from a spicified location
This query retrieves all businesses located within a 5-mile radius of a specific geographical coordinate, sorted by proximity.
The following query requires a new attribute on Business nodes be set. Run this query to set
location on Business nodes.
# Q37. Find all businesses within five miles of the specified location
q37_businesses_with_distance = (
    g.vertices
    .filter(
        (F.col("type") == "business")
        & F.col("latitude").isNotNull()
        & F.col("longitude").isNotNull()
    )
    .withColumn(
        "dist_meters",
        haversine_meters(F.col("latitude"), F.col("longitude"))
    )
)


q37 = (
    q37_businesses_with_distance
    .filter(F.col("dist_meters") <= FIVE_MILES_METERS)
    .select(
        "name",
        "address",
        "city",
        "state",
        "latitude",
        "longitude",
        "dist_meters"
    )
    .orderBy(F.col("dist_meters").asc())
)
Then we build point index with the location values.
Q38. Find the top-10 nearest business to the specific location
This query identifies the 10 nearest businesses to a specific geographical coordinate and ranks them in order of distance.
The following query requires a new attribute on Business nodes be set. Run this query to set
location on Business nodes.
# Q38. Find the top-ten nearest businesses to the specified location
q38_businesses_with_distance = (
    g.vertices
    .filter(
        (F.col("type") == "business")
        & F.col("latitude").isNotNull()
        & F.col("longitude").isNotNull()
    )
    .withColumn(
        "dist_meters",
        haversine_meters(F.col("latitude"), F.col("longitude"))
    )
)

q38 = (
    q38_businesses_with_distance
    .select(
        "name",
        "address",
        "city",
        "state",
        "latitude",
        "longitude",
        "dist_meters"
    )
    .orderBy(F.col("dist_meters").asc())
    .limit(10)
)
Then we build point index with the location values.
Q39. Find reviews containing “disgusting”
This query searches for and returns up to 100 review texts that contain the word "disgusting".
# Q39. Find reviews containing "disgusting"
q39 = (
    g.vertices
    .filter(
        (F.col("type") == "review")
        & F.lower(F.col("text")).contains("disgusting")
    )
    .select("id", "text")
    .limit(100)
)
Equivalent query in GQL standard:
MATCH (r:Review)
WHERE toLower(r.text) CONTAINS "disgusting"
RETURN r.id, r.text
LIMIT 100
Q40. Find the most frequently used words in reviews
This query extracts, filters (length > 3), and ranks the top 20 most frequent individual words used across all review text.
# Q40. Find the most frequently used words in reviews
q40 = (
    g.vertices
    .filter(F.col("type") == "review")
    .select(
        F.explode(
            F.split(F.lower(F.col("text")), " ")
        ).alias("word")
    )
    .filter(F.length("word") > 3)
    .groupBy("word")
    .agg(F.count("*").alias("freq"))
    .orderBy(F.col("freq").desc())
    .limit(20)
)
Equivalent query in GQL standard:
MATCH (r:Review)
UNWIND split(toLower(r.text), " ") AS word
RETURN word, count(*) AS freq
  WHERE size(word) > 3
ORDER BY freq DESC
LIMIT 20